TERRIFIX MESH
One platform for the entire model lifecycle.
Prepare data, select models, fine-tune, evaluate, version, deploy, serve and monitor from one control layer - across the infrastructure your enterprise chooses.
01
Unified
One complete ModelOps path
02
Efficient
More productive GPU capacity
03
Controlled
Your models and environment
01 · Platform overview
The control layer
between your applications and compute.
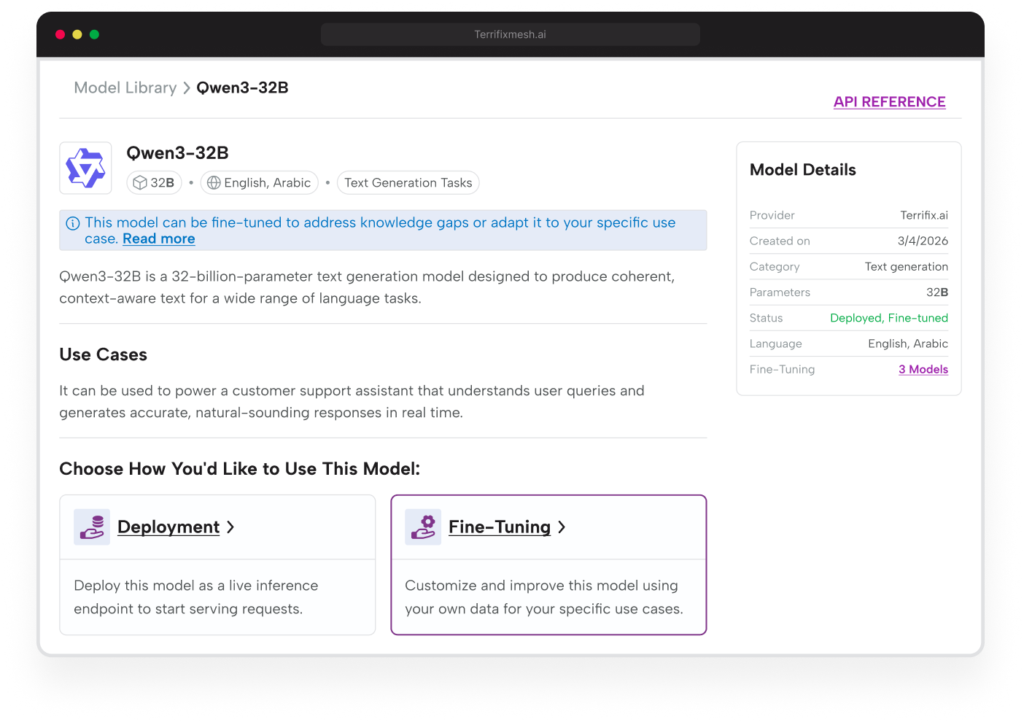
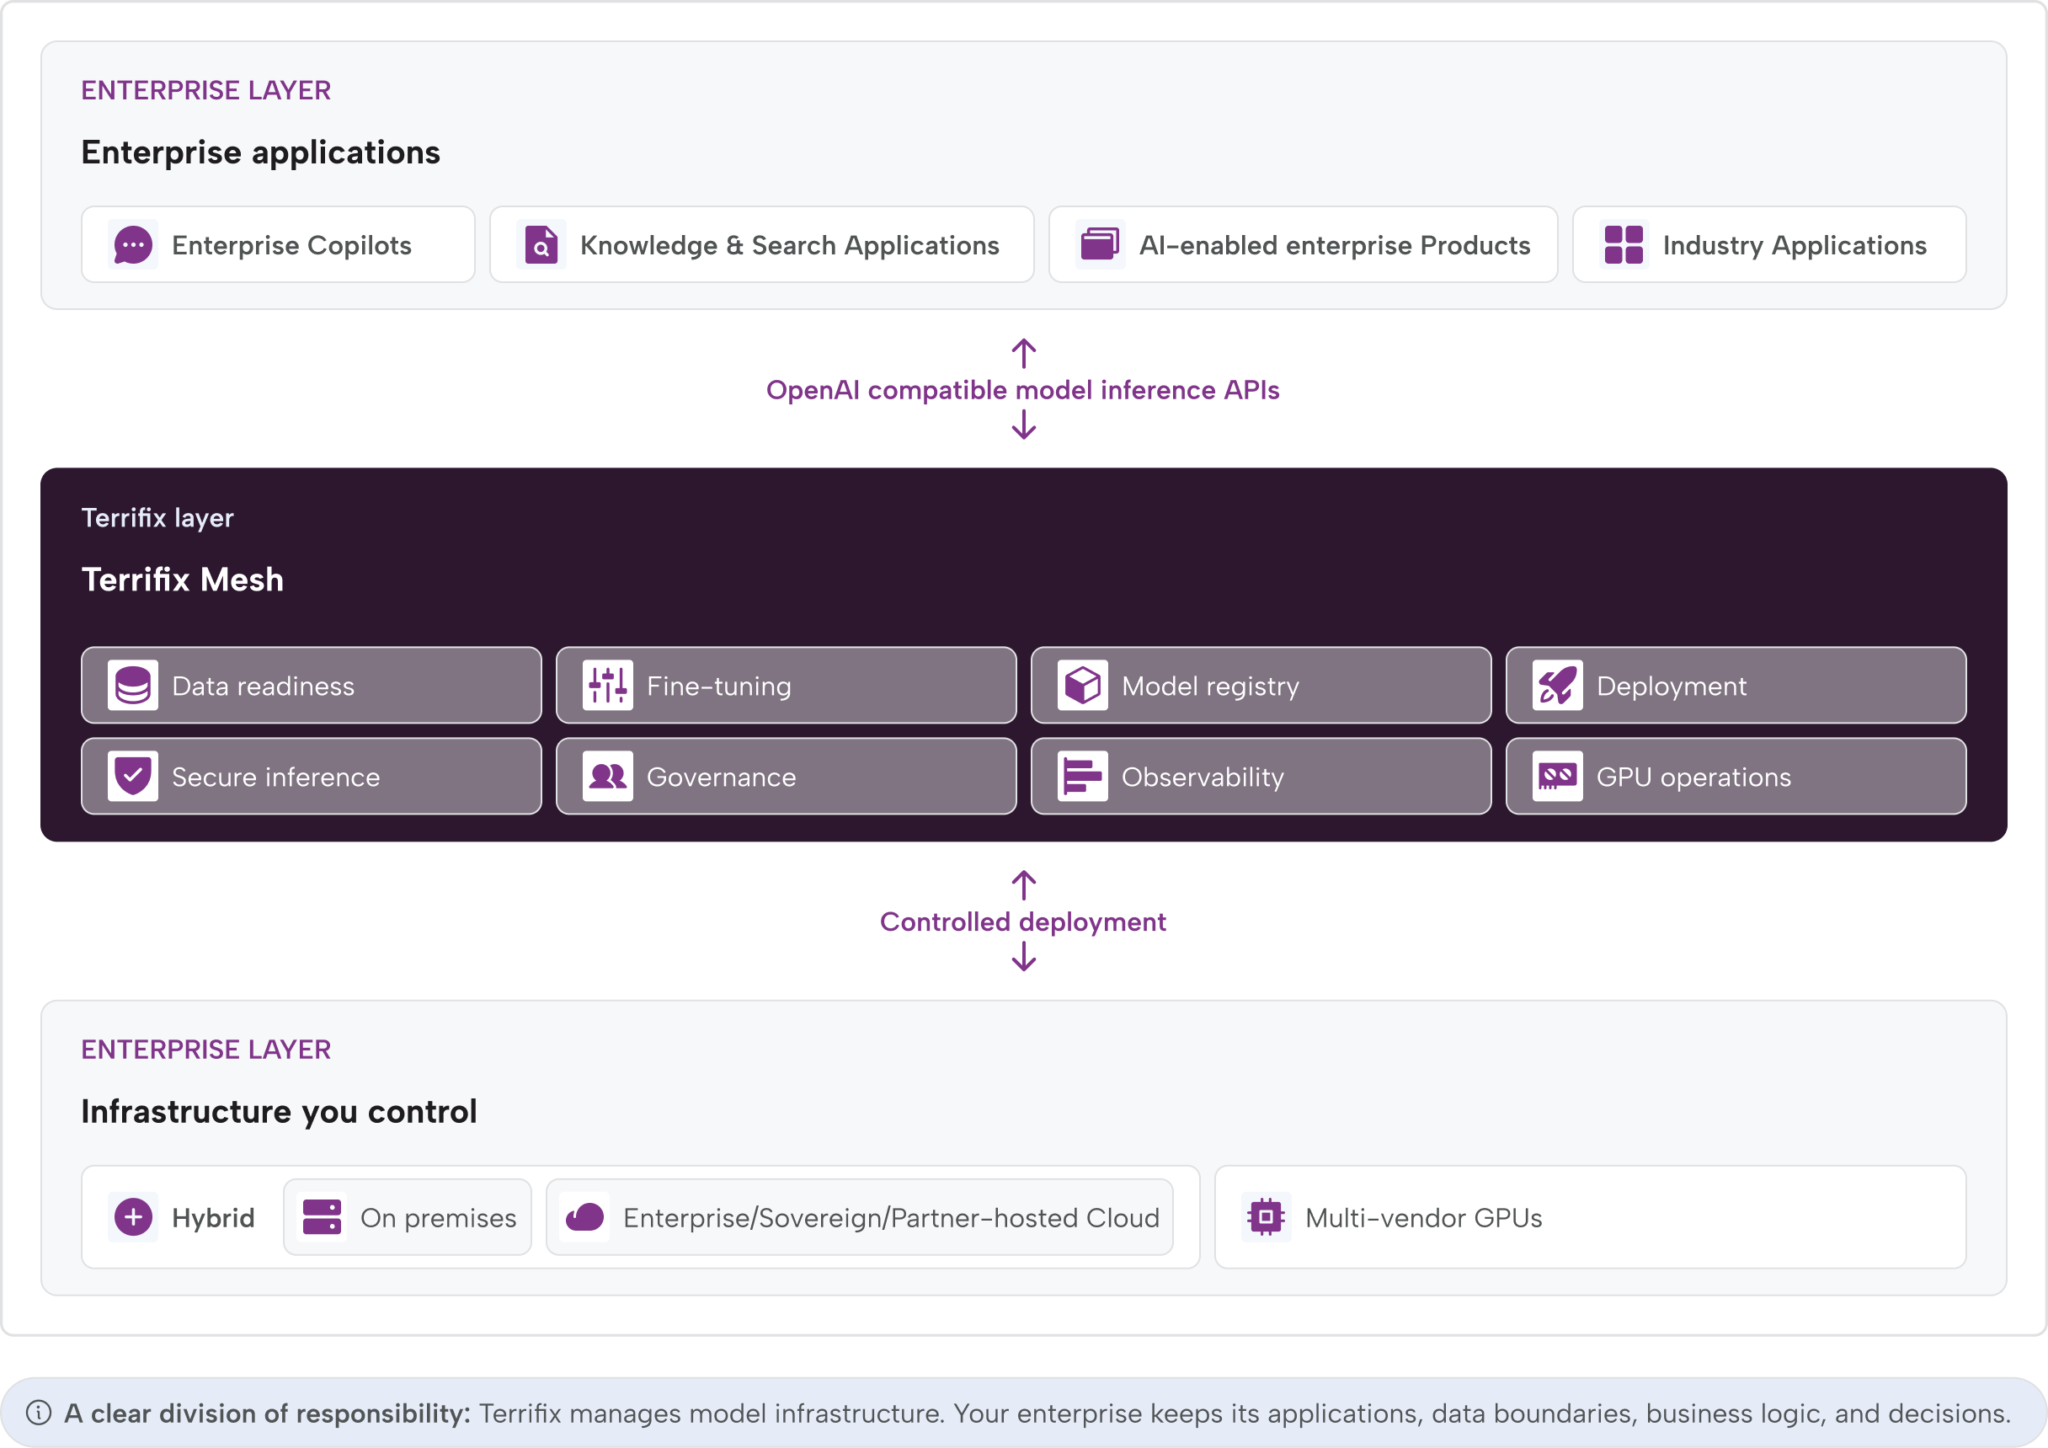
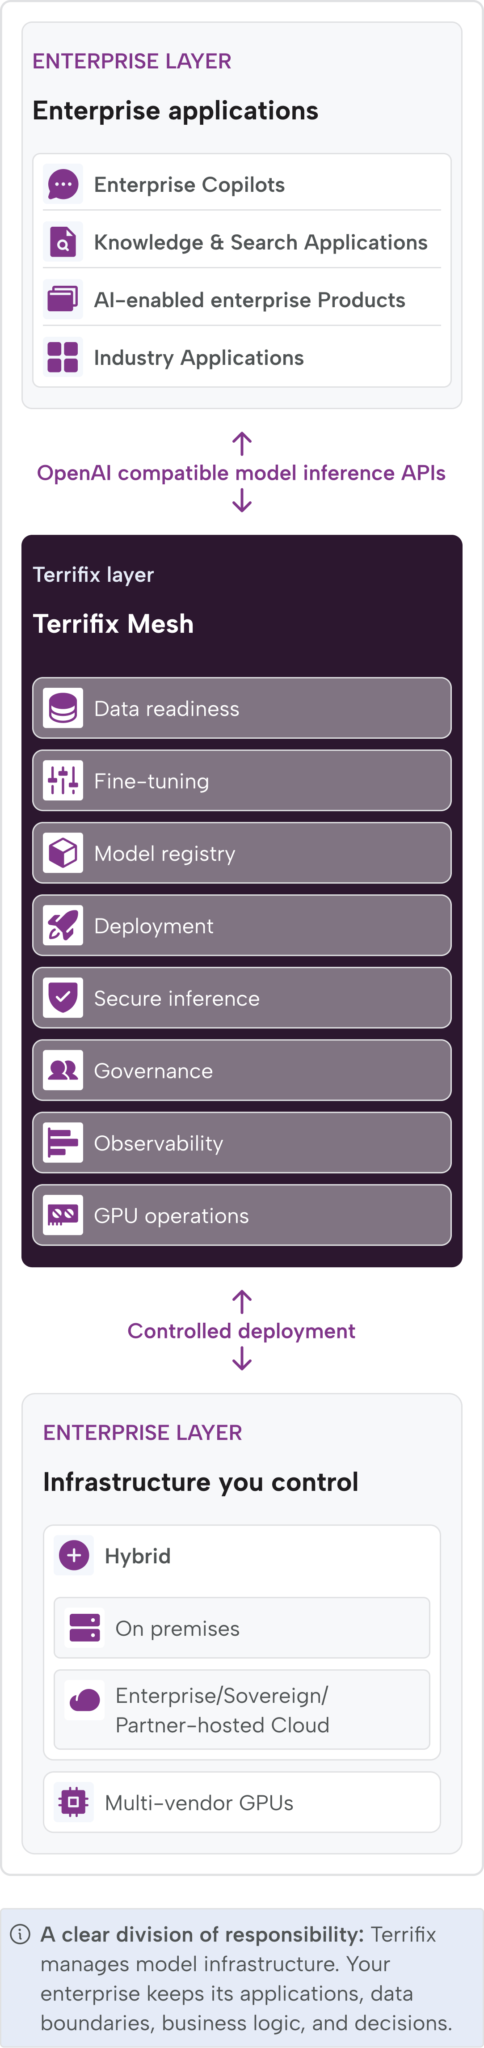
Mesh unifies model lifecycle operations, secure inference and multi-vendor compute orchestration. Applications consume model inference endpoints while business workflows and decisions remain in enterprise systems.
02 · Model lifecycle
One governed path from model selection to production inference.
Mesh coordinates eight controlled stages across the open-weight model lifecycle, with validation, approvals, and traceability built into the path from model selection and fine-tuning to deployment and production inference.
01
Select model
Choose the approved open-weight foundation model that fits the target workload and infrastructure.
- Start with the right fit
02
Prepare and submit data
Structure authorized training data and submit a repeatable model configuration.
- Turn data into a controlled job
03
Validate data quality
Apply preflight checks before GPU capacity is committed to the training run.
- Protect compute spend
04
Fine-tune
Run controlled training jobs that adapt the model to approved enterprise context.
- Build relevant intelligence
05
Evaluate gates
Review enterprise-defined evaluation evidence and control which model can progress.
- Keep approval deliberate
06
Register version
Record the exact approved artifact, configuration and lineage in the model registry.
- Know what is running
07
Deploy endpoint
Serve the approved version through a secured, OpenAI-compatible inference endpoint.
- Connect enterprise applications
08
Observe, audit,& improve
Correlate system, GPU, fine-tuning and inference signals around the deployed version.
- Operate with evidence
03 · Data readiness and fine-tuning
Turn enterprise data into controlled model variants.
Teams prepare training inputs, configure jobs and track fine-tuning from one operating environment.
04 · Deployment and inference
Serve models through secure, production-ready inference endpoints.
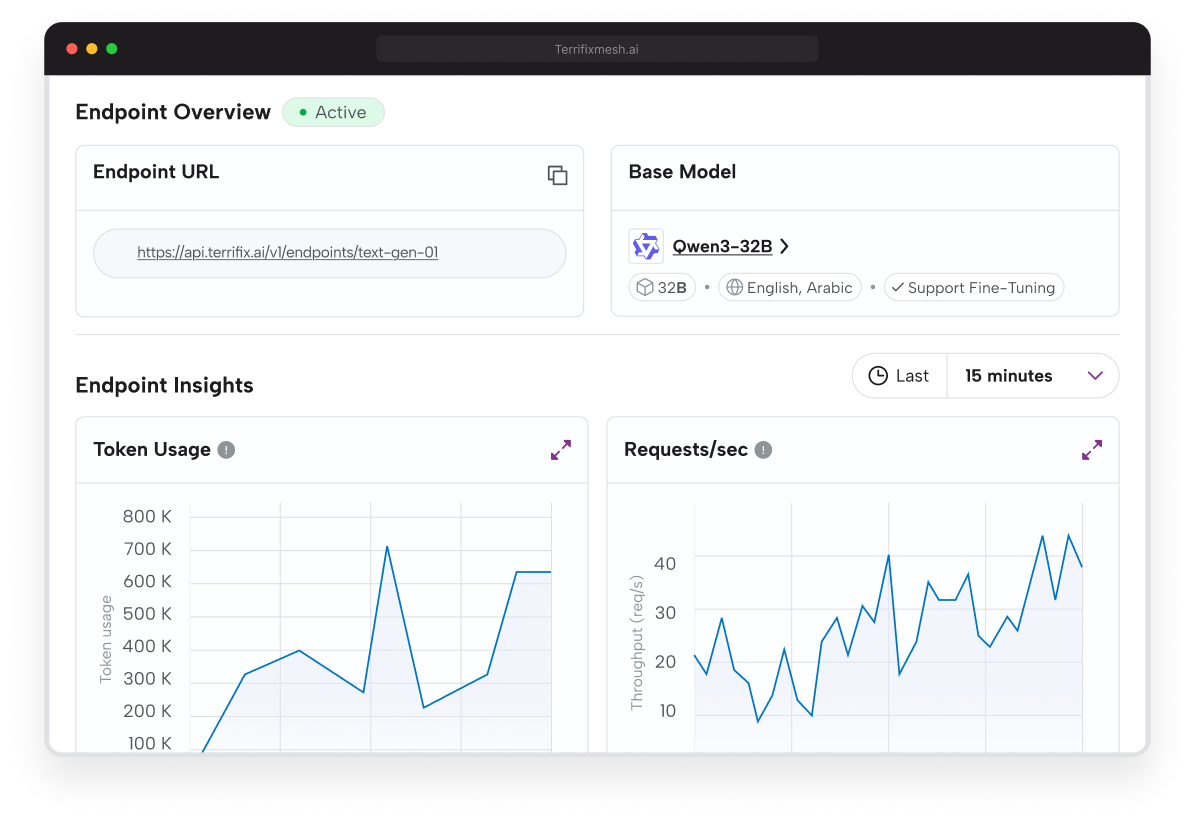
Mesh turns registered artifacts into controlled endpoints that enterprise applications consume through a stable model API.
01
OpenAI-compatible inference APIs
Connect applications without redesigning their model integration layer.
02
Exact-version deployment
Serve the immutable, approved model artifact recorded in the registry.
03
Endpoint security and isolation
Apply authentication, access control and tenant boundaries to model access.
04
Engine-agnostic orchestration
Coordinate the serving runtime, scaling and GPU placement for the model footprint.
PLATFORM ARCHITECTURE
A platform built as a complete AI system
Terrifix.ai is not just a set of features, it’s a layered platform where each component works as part of a unified system.
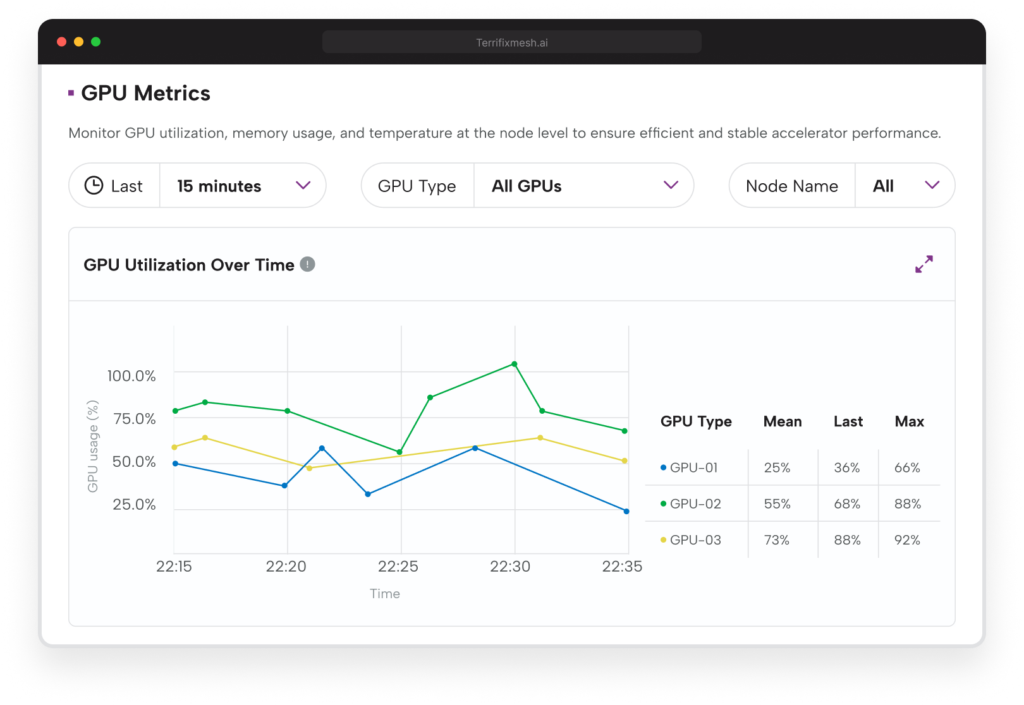
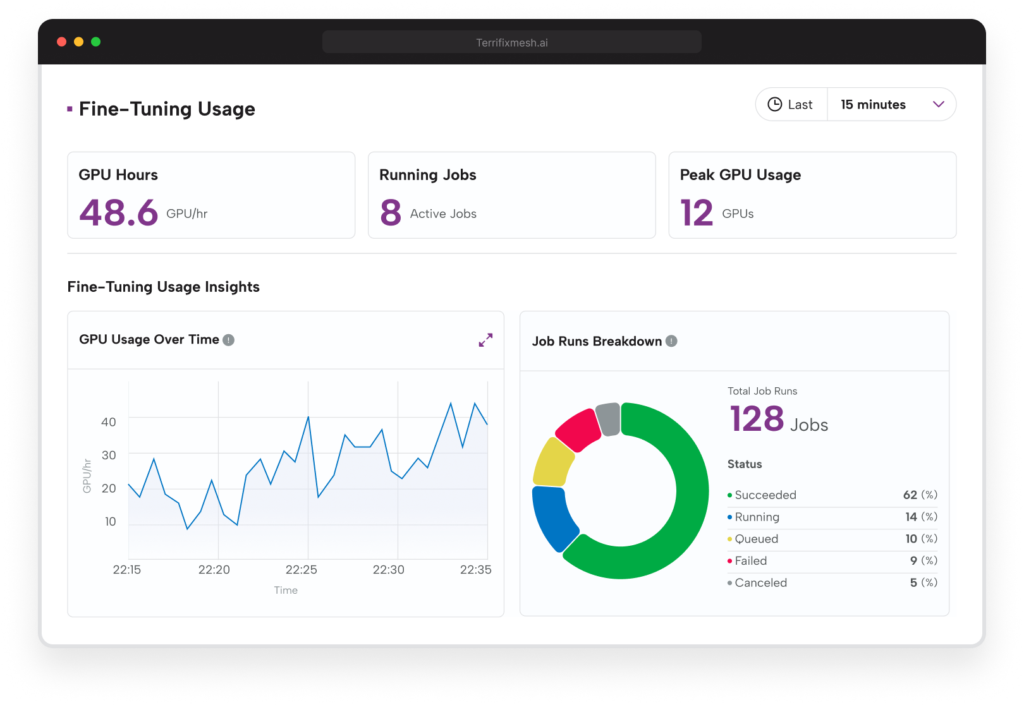
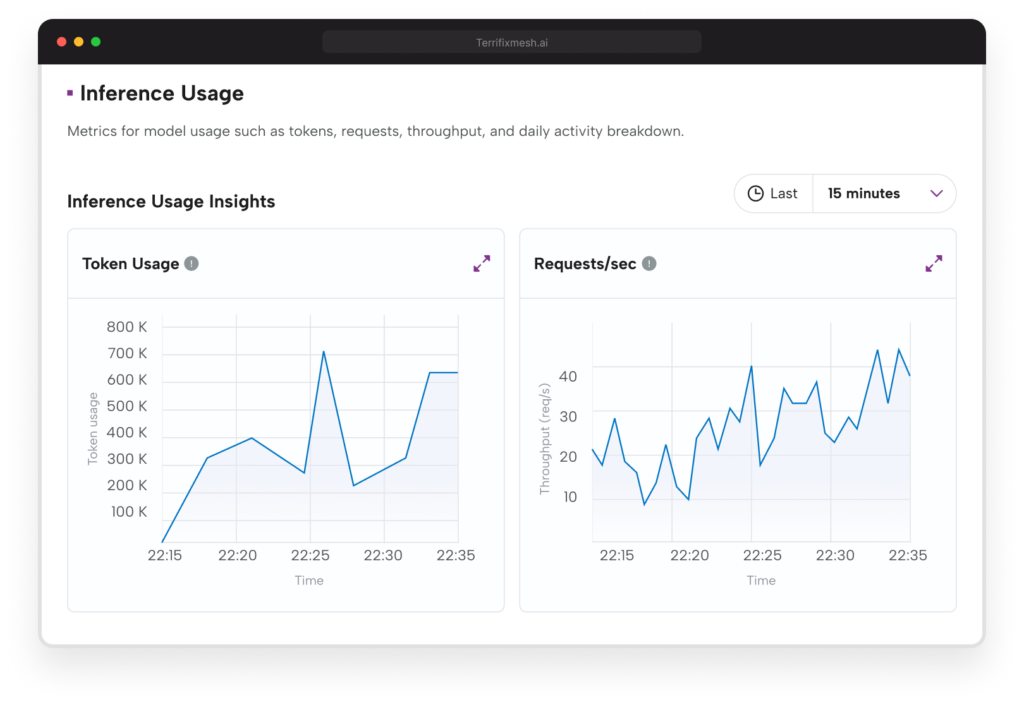
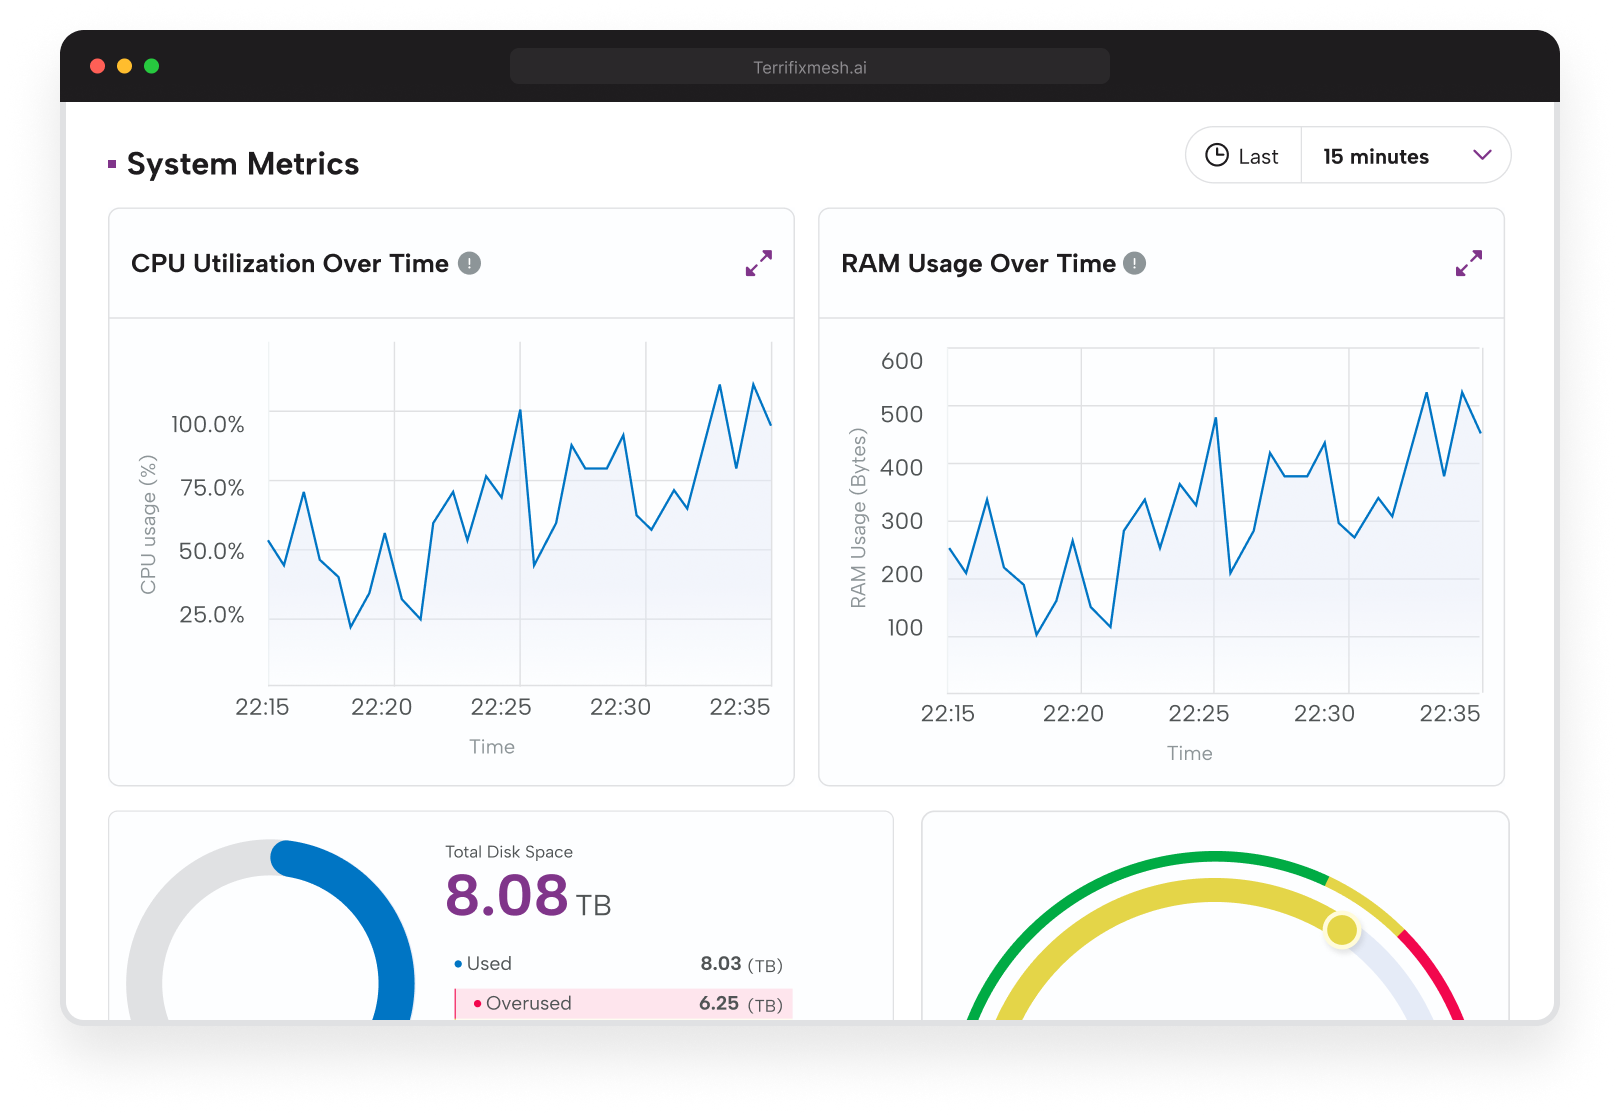
06 · Correlated observability
Trace production behavior back to the model that produced it.
Mesh connects system, GPU, fine-tuning and inference signals around the same jobs, model versions and endpoints—keeping operational and audit evidence aligned.
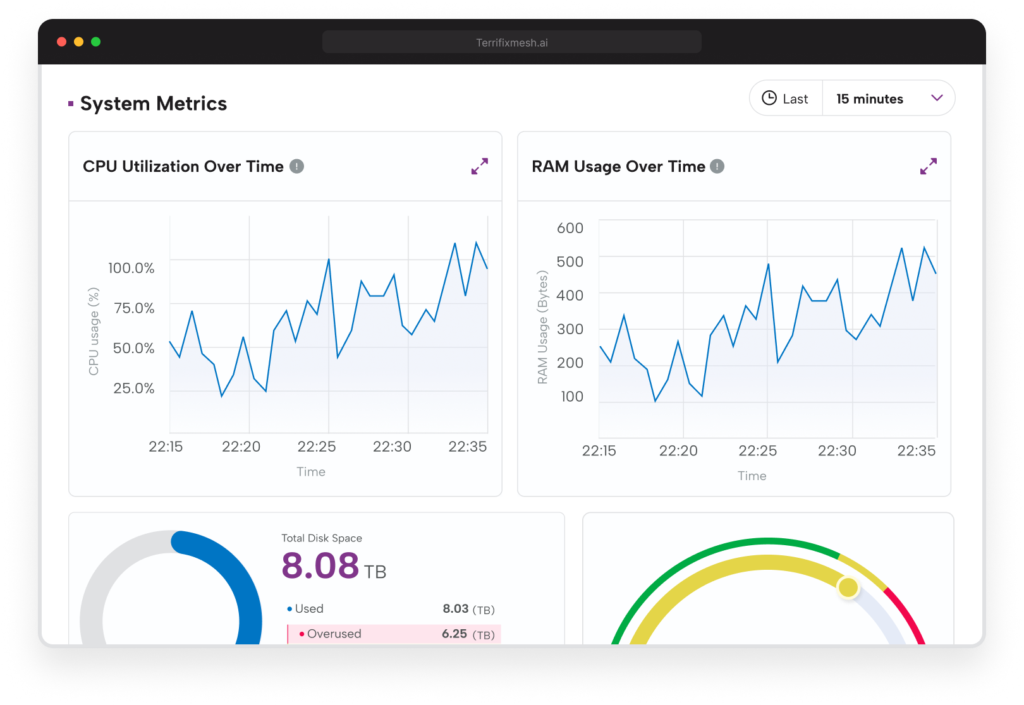
System metrics
Monitor service and cluster health.
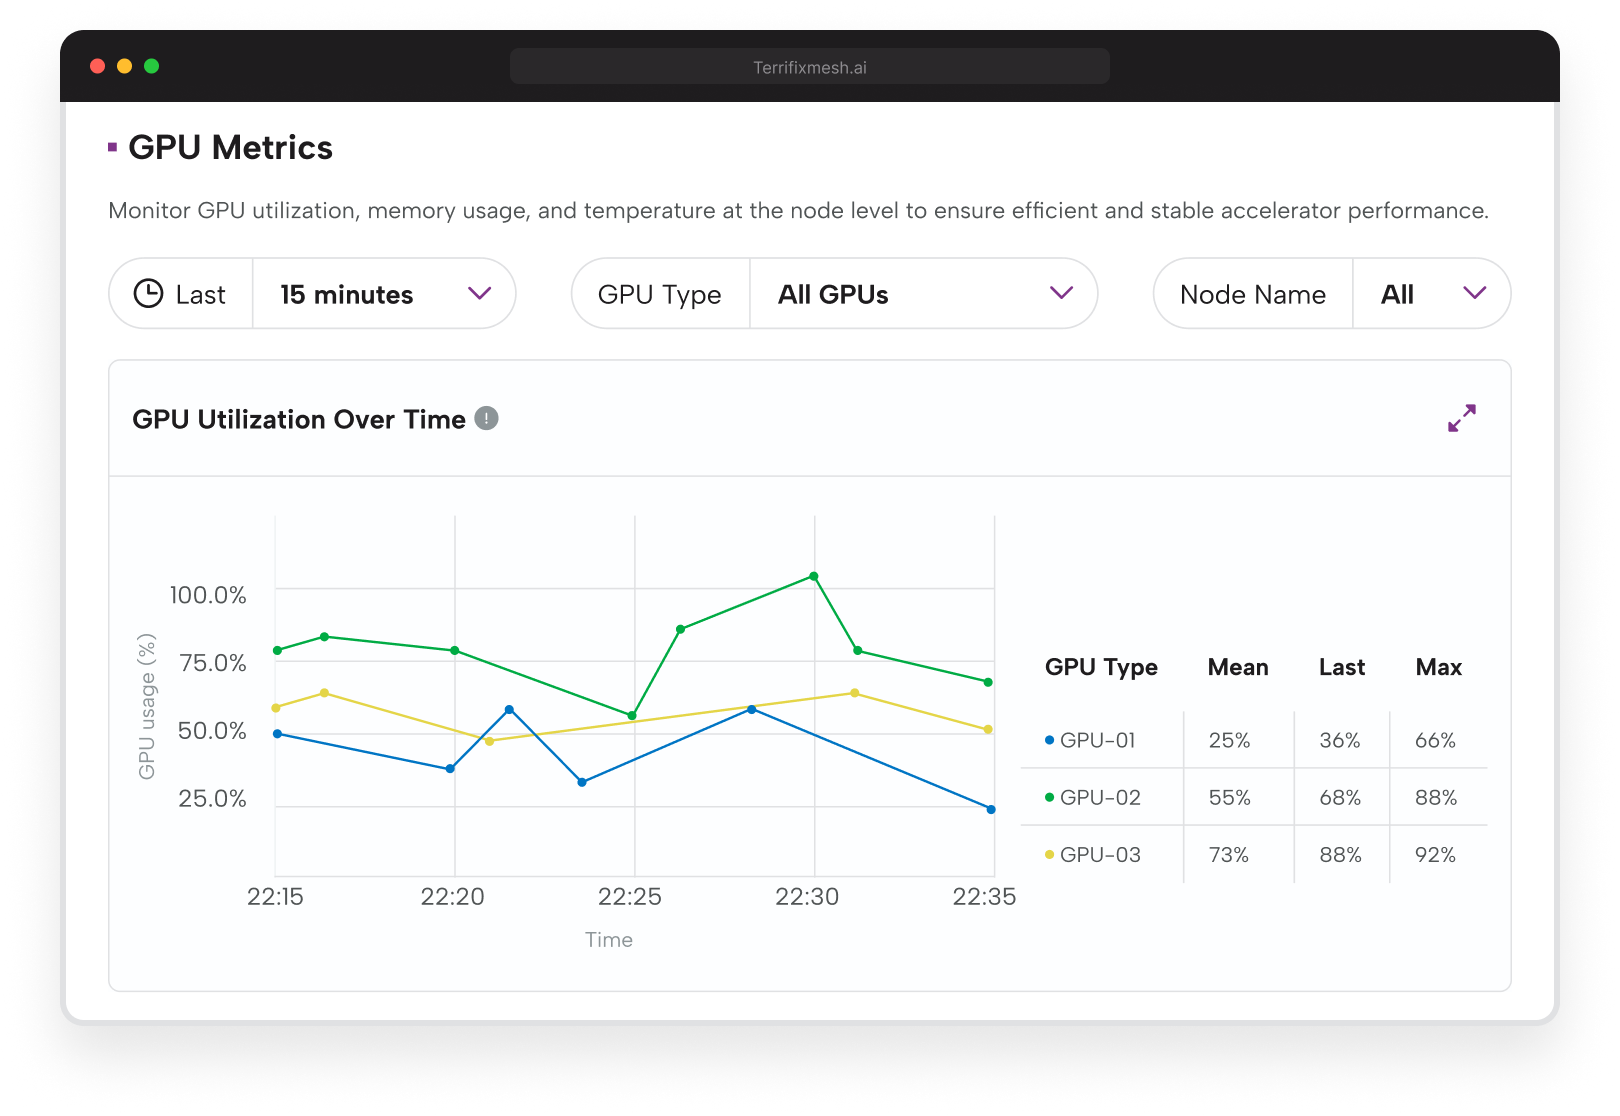
GPU metrics
See allocation, utilization and capacity.
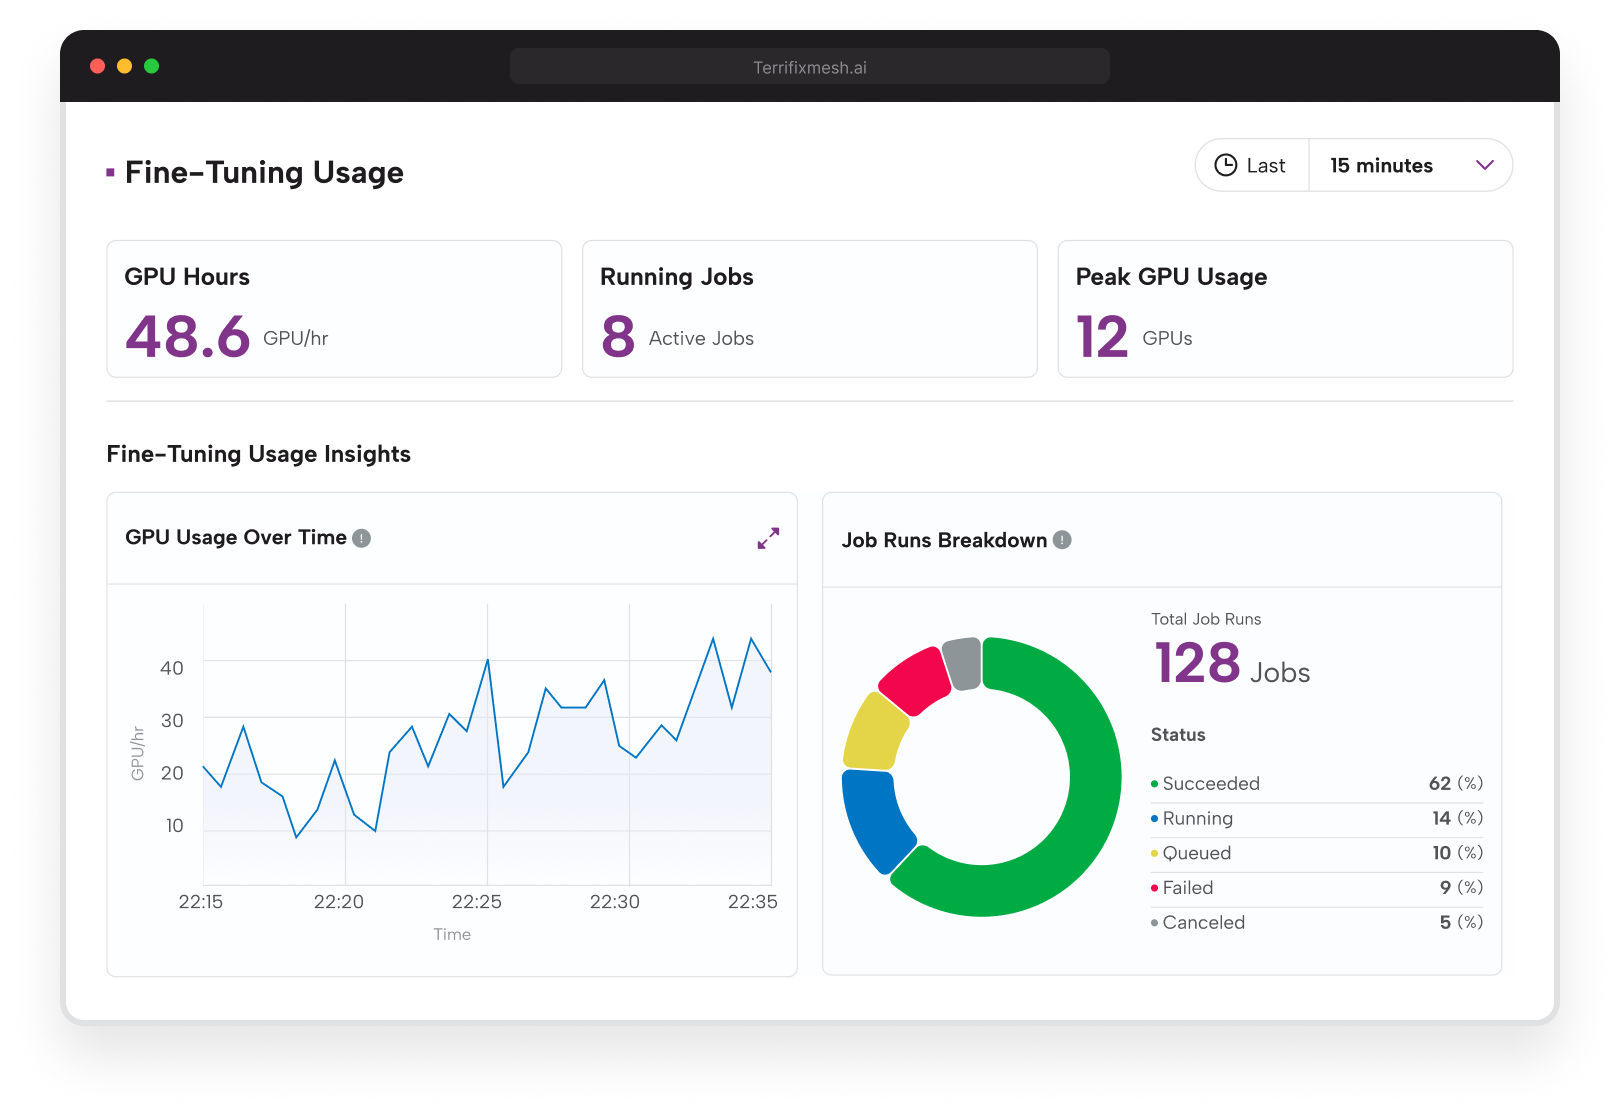
Fine-tuning metrics
Track job progress, checkpoints and training signals.
Inference metrics
Observe endpoint traffic, latency and errors.
07 · Infrastructure-agnostic compute
Turn every GPU estate into one compute fabric.
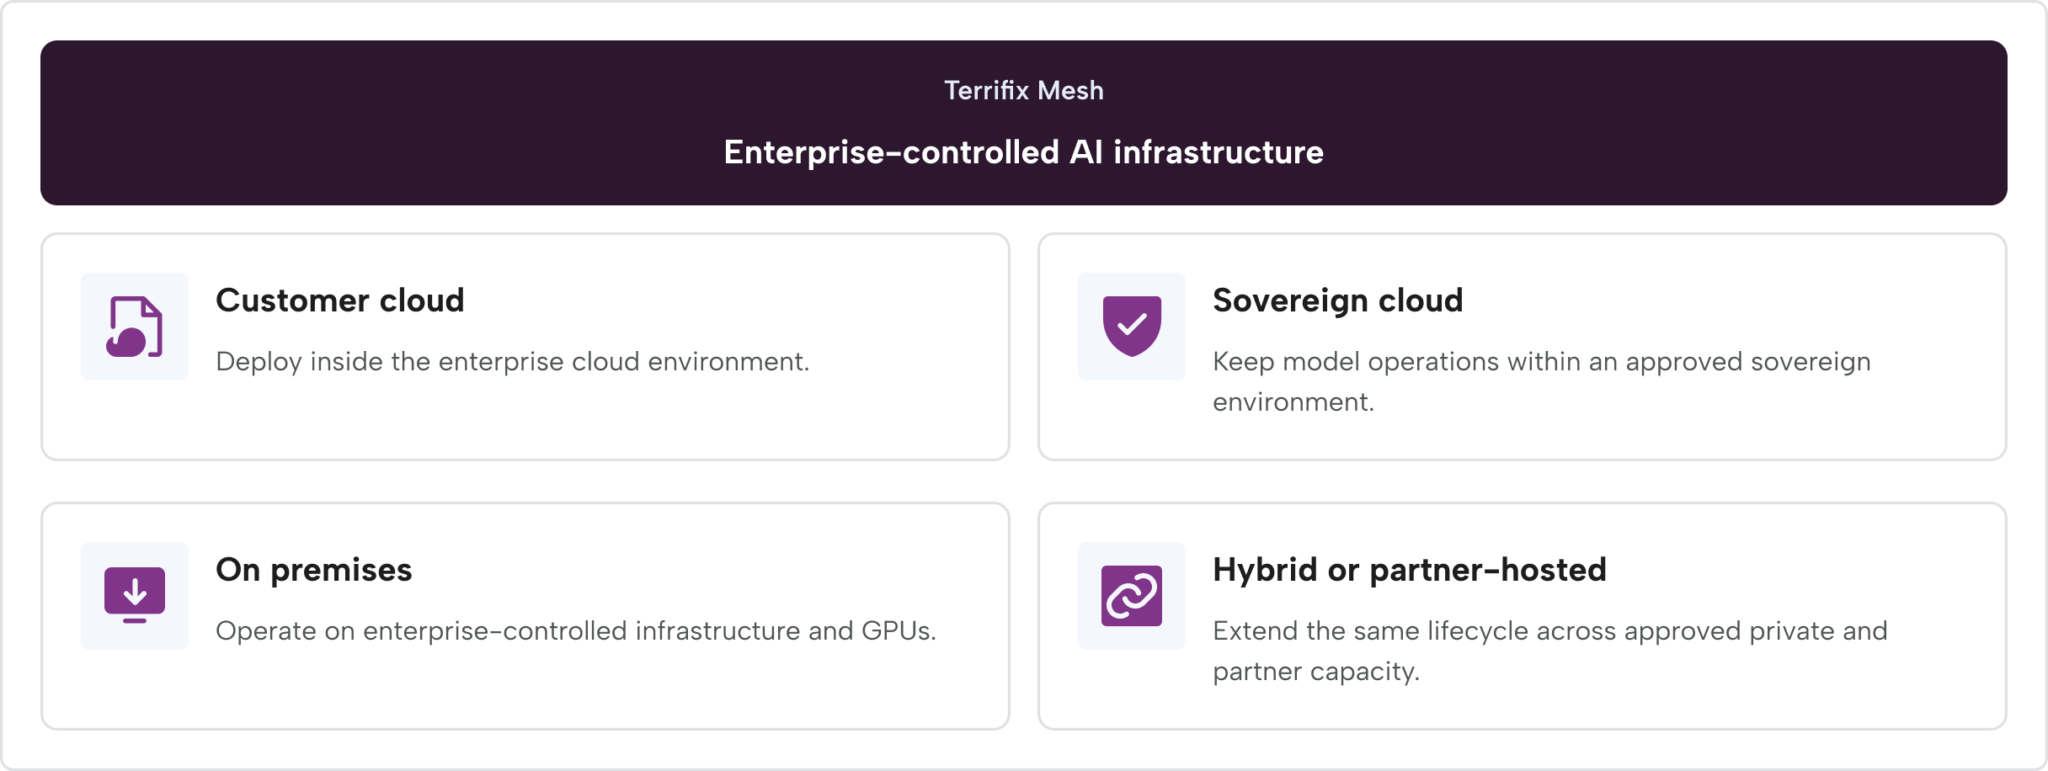
Mesh is infrastructure-agnostic. It coordinates supported multi-vendor GPU capacity across enterprise-controlled Kubernetes, cloud, sovereign-cloud and on-premises environments under one operating layer.
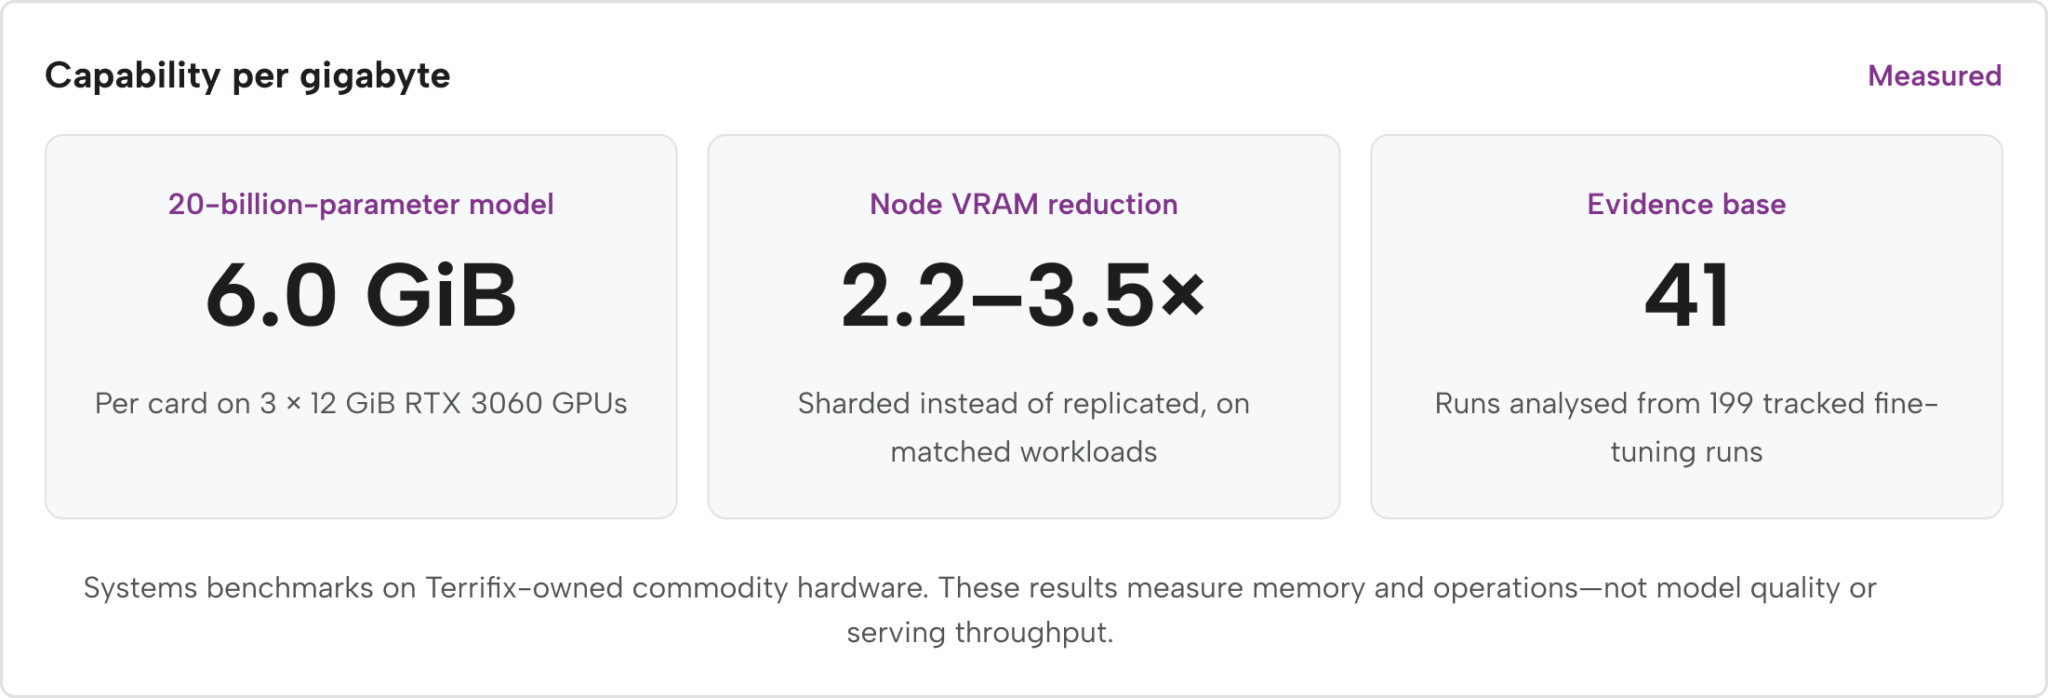
08 · Measured systems evidence
Optimize every layer.
Make every GPU carry more AI.
Terrifix applies proprietary, patent-pending optimization across model training, serving and compute operations to improve GPU productivity and reduce repeated engineering effort.
JOIN US
Ready to evaluate Mesh in your environment?
Start with your target model, infrastructure environment and the use case you want to move into production.